Looking for the latest information on Continuous Batching Explained? We've researched comprehensive data, records, and insights about Continuous Batching Explained.
Core Information
Explore the main sources for Continuous Batching Explained.
Latest News
Stay updated on Continuous Batching Explained's newest achievements.
Continuous Batching: Optimize LLM Serving Throughput and Latency
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference
Continuous Batching Explained | vLLM vs TGI vs SGLang | LLM Inference Optimization & PagedAttention
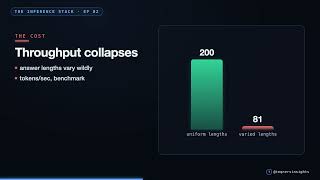
The Waiting GPU: Continuous Batching Explained - 23x From One GPU
vLLM Fully explained page attention & continuous batching in simple way
Continuous Batching: AI's Engine
What is Continuous Batching
Chunked prefill, ragged batching and continuous batching
Continuous Batching Explained: Iteration-Level Scheduling in vLLM (Orca Paper)
Deep Dive: Optimizing LLM inference
What's the Difference Between a Continuous and Batch Process
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: September 22, 2026
Future Outlook
For 2026, Continuous Batching Explained remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... If you want to deploy an LLM endpoint, it is critical to think about how different requests are going to be handled. In typical ... cefboud.com/posts/inside-llm-inference-engine-nano-vllm- For the LLM inference serving techniques, We will cover Orca: In this video, we dive deep into Ever wondered how ChatGPT, DeepSeek, Claude, Gemini, and other Large Language Models (LLMs) can serve thousands of ... Your inference GPU costs $30 an hour and works about 30% of the time. Not broken - scheduled wrong. Episode 2 of The ... Want to make your Large Language Models (LLMs) run faster and more efficiently? In this video, I The provided technical article outlines the fundamental mechanisms and optimization techniques necessary to understand and ... A code-focused walkthrough of Chunked prefill, ragged 00:00 Introduction 01:15 Decoder-only inference 06:05 The KV cache 11:15 Want to learn industrial automation? Go here: realpars.com ▷ Want to train your team in industrial automation? Go here: ...