Looking for the latest information on Temporal Difference Methods? We've researched comprehensive data, records, and insights about Temporal Difference Methods.
Key Details
Explore the key sources for Temporal Difference Methods.
Recent Updates
Stay updated on Temporal Difference Methods's latest milestones.
TD Learning - Richard S. Sutton
Proximal Algorithms and Temporal Difference Methods
RL 8: Value function approach - Temporal Difference Reinforcement Learning - SARSA Algorithm
Passive Reinforcement Learning-Artificial Intelligence-20A05502T-UNIT III
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 22, 2026
Future Outlook
For 2026, Temporal Difference Methods remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
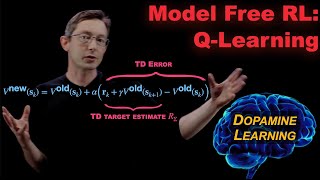
Reach out to us :) truetheta.io Part four of a six part series on Reinforcement Learning. As the title says, it covers Let's talk about the foundation concept of Q-learning, SARSA called Here we describe Q-learning, which is one of the most popular Copyright belongs to videolecture.net, whose player is just so crappy. Copying here for viewers' convenience. Deck is at the ... Video from a January 2017 slide presentation on the relation of Proximal Algorithms and Don't the Sound Effect?:* youtu.be/eY08RHDphKo *Full Reinforcement Learning Playlist:* ... Link to the slides: videolectures.net/site/normal_dl/tag=1137922/deeplearning2017_sutton_td_learning_01.pdf DeepMind ... Full Course HERE :* sds.courses/ai-az How do AI agents learn from experience? In this video, we break down temporaldifference Here we introduce the idea of Telegram group : t.me/joinchat/G7ZZ_SsFfcNiMTA9 contact me on Gmail at shraavyareddy810 contact me on ... Free PDF: incompleteideas.net/book/RLbook2018.pdf Print Version: ... UNIT III – Reinforcement Learning and Natural Language Processing Passive Reinforcement Learning Passive Reinforcement ...