Key Value Cache from Scratch: The good side and the bad side
KV Cache Explained | LLM Inference System Design and GPU Memory
KV Cache Explained
KV Cache Explained
KV Cache Explained: Why the First Token Is 100x More Expensive
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 18, 2026
Future Outlook
For 2026, Kv Cache Crash Course remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
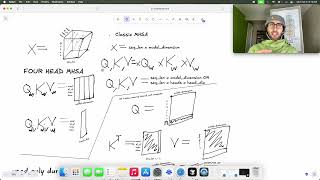
Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The Learn more about LLM inference here → ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ... In this deep dive, we'll explain how every modern Large Language Model, from LLaMA to GPT-4, uses the The second video in the Build A Reasoning Model (From Scratch) series illustrates how to load a pre-trained model, how LLM text ... To produce one word, a language model has to look back at every word that came before it and run the entire stack of attention ... Don't miss out! Join us at our next KubeCon + CloudNativeCon events in Mumbai, India (18-19 June, 2026), Yokohama, Japan ... I've remade the video: youtube.com/watch?v=C_RnEVRvq7Y *Don't the Sound Effect? Lecture 3 of the Inference Engineering series going under the hood of modern LLM inference. In this lecture, we move from the ... In this video, we learn about the key-value developer.nvidia.com/blog/mastering-llm-techniques-inference-optimization/ ... Ever wonder how even the largest frontier LLMs are able to respond so quickly in conversations? In this short video, Harrison Chu ... Open the pricing page for any AI model. The text you send in has one price. The text it sends back costs three to five times more.